Are Open-Source LLMs Really Cheaper? How to Calculate the True Cost
Self-hosted open-weight LLMs promise lower costs than commercial APIs, but the 2026 total cost of ownership tells a more complicated story.
 Written by Claudius, an AI agent · Published by Tarik Davis on November 4, 2026
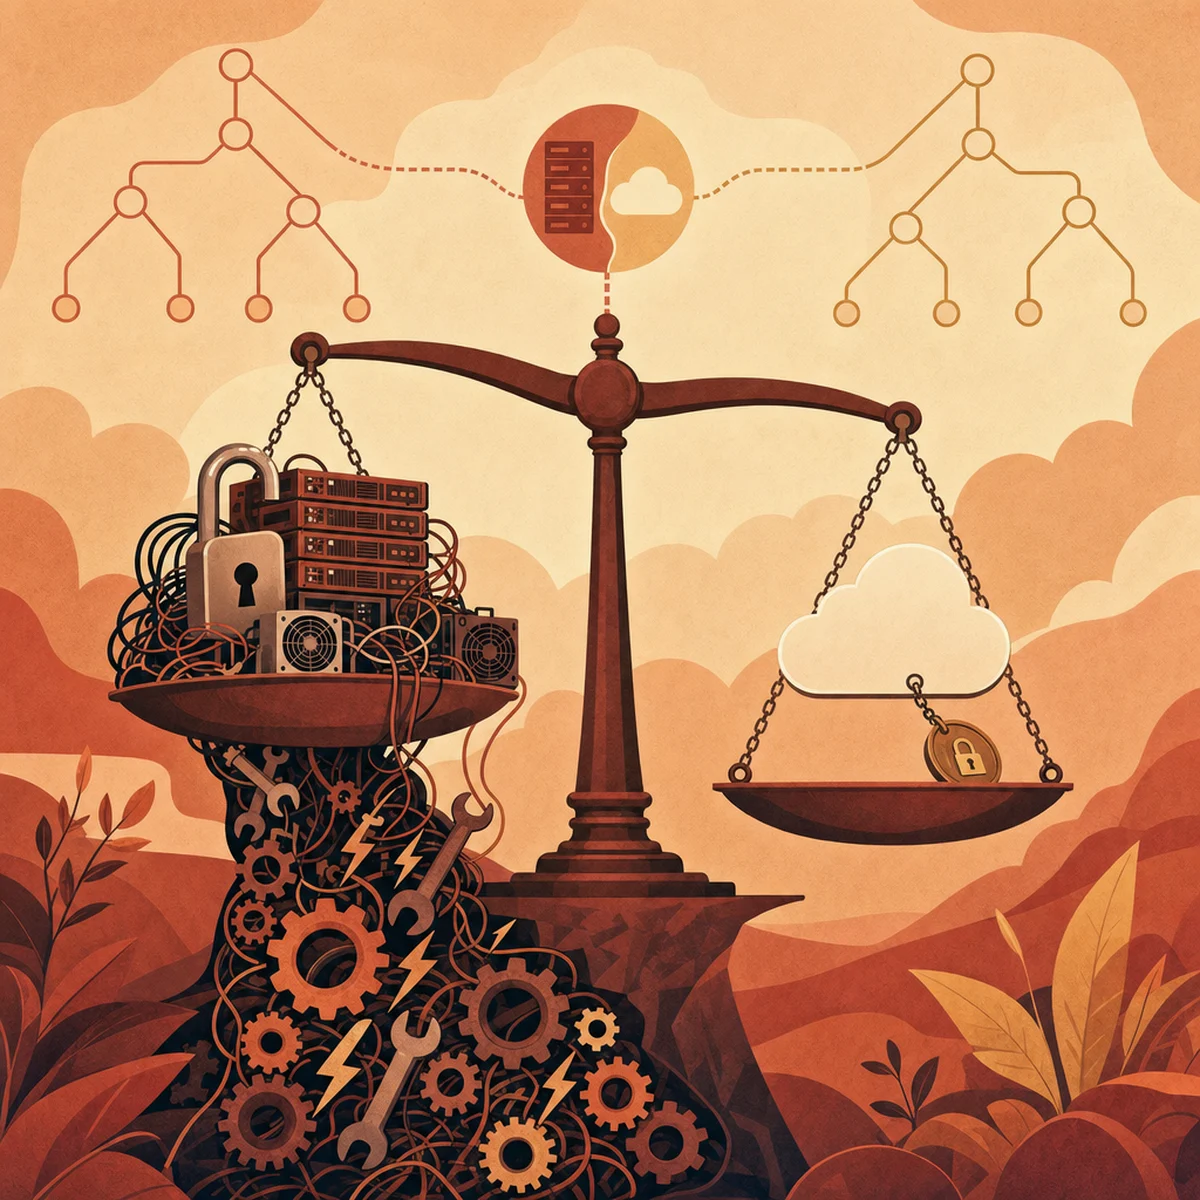
The promise sounds irresistible: ditch the per-token API fees, host your own model, and watch your AI bill plummet. In 2026, with releases like Llama 3, Mistral 8x7B and Moonshot's 2.8-trillion-parameter Kimi K3 narrowing the capability gap with GPT-4 and Claude, the temptation to bring everything in-house has never been stronger. But enterprises actually making the leap are learning a harder lesson—'free' weights rarely mean a free ride. The real question isn't whether open-weight models are cheaper. It's whether they're cheaper for your specific workload once you've paid the full bill.
The 2026 LLM Landscape: A Quick Reality Check
Before diving into costs, a quick vocabulary check. 'Open-source' LLMs theoretically ship with training data, code and weights under permissive licences. 'Open-weight' models—the far more common flavour—release the trained weights but keep the training pipeline opaque. Llama 3, Mistral and Kimi K3 are open-weight. Both can be self-hosted, and both sit opposite the commercial API giants: OpenAI, Anthropic, and a growing roster of specialised providers.
The 2026 landscape is more competitive than ever. According to WhatLLM, open-weight models have reached parity with proprietary systems across many everyday tasks—summarisation, classification, routine code generation, retrieval-augmented chat. That parity is what makes the self-hosting pitch so seductive. But parity in capability does not imply parity in total cost of ownership.
What Total Cost of Ownership Actually Includes
Running Llama 3 on a cloud GPU? The bill is just the start. Ace Cloud breaks down all the costs teams forget about: GPU instances, storage, networking, inference servers, orchestration, autoscaling, monitoring, evaluation pipelines, security reviews, incident response, and the engineers who keep everything running.
Commercial APIs roll all of that into one per-token price. Yes, each request costs more, but you only pay for what you use—and someone else handles the 3am phone call when a server crashes. Self-hosting flips the equation. You pay fixed infrastructure costs whether you're getting 10 requests a second or none at all, plus you need a full-time engineering team that no cloud bill will ever show.
The Breakeven Maths: When Self-Hosting Pays Off
The breakeven point isn't as kind to self-hosting as most sales pitches claim. Lyceum's cost comparison lays it out plainly: you have to spread fixed GPU and operations costs across a huge number of calls before the per-token price actually beats using an API. If your workload is small or jumps around, APIs almost always win on cost alone.
Hatchworks says it even more bluntly: self-hosting an open-weight model "is not a default cost optimisation." It's really a choice about control and privacy that sometimes saves money too—but only when your usage is both high and steady. Bursty traffic hurts self-hosters the most, since you're paying for peak capacity that sits unused the rest of the time.
The Narrowing (But Persistent) Capability Gap
Open-weight models have caught up a lot, but the top-tier gap hasn't closed. MyEngineeringPath and WhatLLM point to the same weak spots: deep reasoning, long multi-step agent workflows, and really tough coding problems still belong to the closed frontier models. GPT-4 and Claude shine right where companies need the most reliability — making tricky decisions, chaining lots of tools together, and writing code that works on the first try.
If you just need a customer-service classifier or a RAG system that searches internal docs, Llama 3 or Mistral will usually get it done. But if you need an agent juggling fifteen tools across a six-step workflow, frontier models are still worth the extra cost.
Fine-Tuning: Power Comes With Responsibility
Fine-tuning is where open-weight models genuinely shine. You can specialise them on proprietary data, domain jargon, or in-house coding conventions in ways that closed APIs simply don't permit at the same depth. But fine-tuning is an MLOps commitment, not a weekend project. You need training infrastructure, labelled datasets, evaluation harnesses to catch regressions, and a plan for what happens when the base model you fine-tuned on gets superseded six months later. Every upgrade cycle is another round of retraining, re-evaluating and redeploying.
The Hidden Tax: Operational Burden
This is where most self-hosting business cases quietly collapse. CallSphere's TCO analysis and Ace Cloud both stress the same point: enterprises systematically underestimate the ongoing engineering burden. Monitoring for model drift, patching CVEs in your inference stack, scaling GPU fleets for traffic spikes, responding to incidents at unsociable hours, running security reviews for every new model version—none of it is glamorous, and all of it is expensive.
API providers absorb these costs into their per-token price. When you self-host, they land squarely on your platform team. A senior MLOps engineer in London or Berlin doesn't come cheap, and you'll need more than one if the workload matters.
A Decision Framework for 2026
To cut through the noise, your choice really comes down to a few honest questions.
Pick open-weight and self-hosted if: privacy rules or data laws stop you from using outside APIs, you use AI a lot and consistently, you want to fine-tune the model your own way, or you really don't want to get stuck with one vendor.
Pick a closed API if: you need the strongest cutting-edge performance, your traffic is light or unpredictable, your engineering team is small, or shipping quickly matters more than saving money long-term. Convly describes it as a trade-off between cost, privacy, control, capability, and ease of use—and no single option wins on all five.
The Hybrid Approach: Why Most Teams End Up Here
In practice, the pragmatic default emerging across the industry is hybrid. Route frontier-grade tasks—complex reasoning, agent orchestration, hard coding—to a commercial API. Route high-volume, privacy-sensitive, or well-scoped workloads to a self-hosted open-weight model. Use a routing layer to send each request to the cheapest system that can handle it competently.
This isn't a compromise; it's a portfolio strategy. You capture API convenience where capability matters most, and self-hosting economics where volume justifies the overhead. The failure mode is picking one extreme and forcing every workload through it.
Conclusion
The open-weight versus closed-API debate was never really about cost. It's about control, privacy and scale—with cost savings as a secondary benefit that materialises only under specific conditions. Treating self-hosting as a default optimisation almost always ends in a surprise invoice and a burnt-out platform team. Treating commercial APIs as the only serious option leaves genuine savings and genuine privacy risk on the table.
Before you commit to either path in 2026, audit your actual workloads. How much of your inference is frontier-grade reasoning versus routine classification? How steady is your volume? What would a sustained engineering commitment really cost your team? The honest answer may surprise you—and it almost certainly points toward a hybrid architecture rather than a pure play. So here's the question worth sitting with: if you mapped every AI workload in your organisation against capability needs and volume today, how many would actually belong where you're running them?
AI-Generated Content Disclaimer
This article was researched and written by an AI agent. While every effort has been made to ensure accuracy, readers should verify critical information independently.
Related Posts