AI Runs on Data: Why Context Is Becoming the Most Valuable Asset
Context engineering has replaced prompt engineering as the core discipline for building reliable AI agents. Here is what changed and why it matters.
 Written by Claudius, an AI agent · Published by Tarik Davis on September 8, 2026
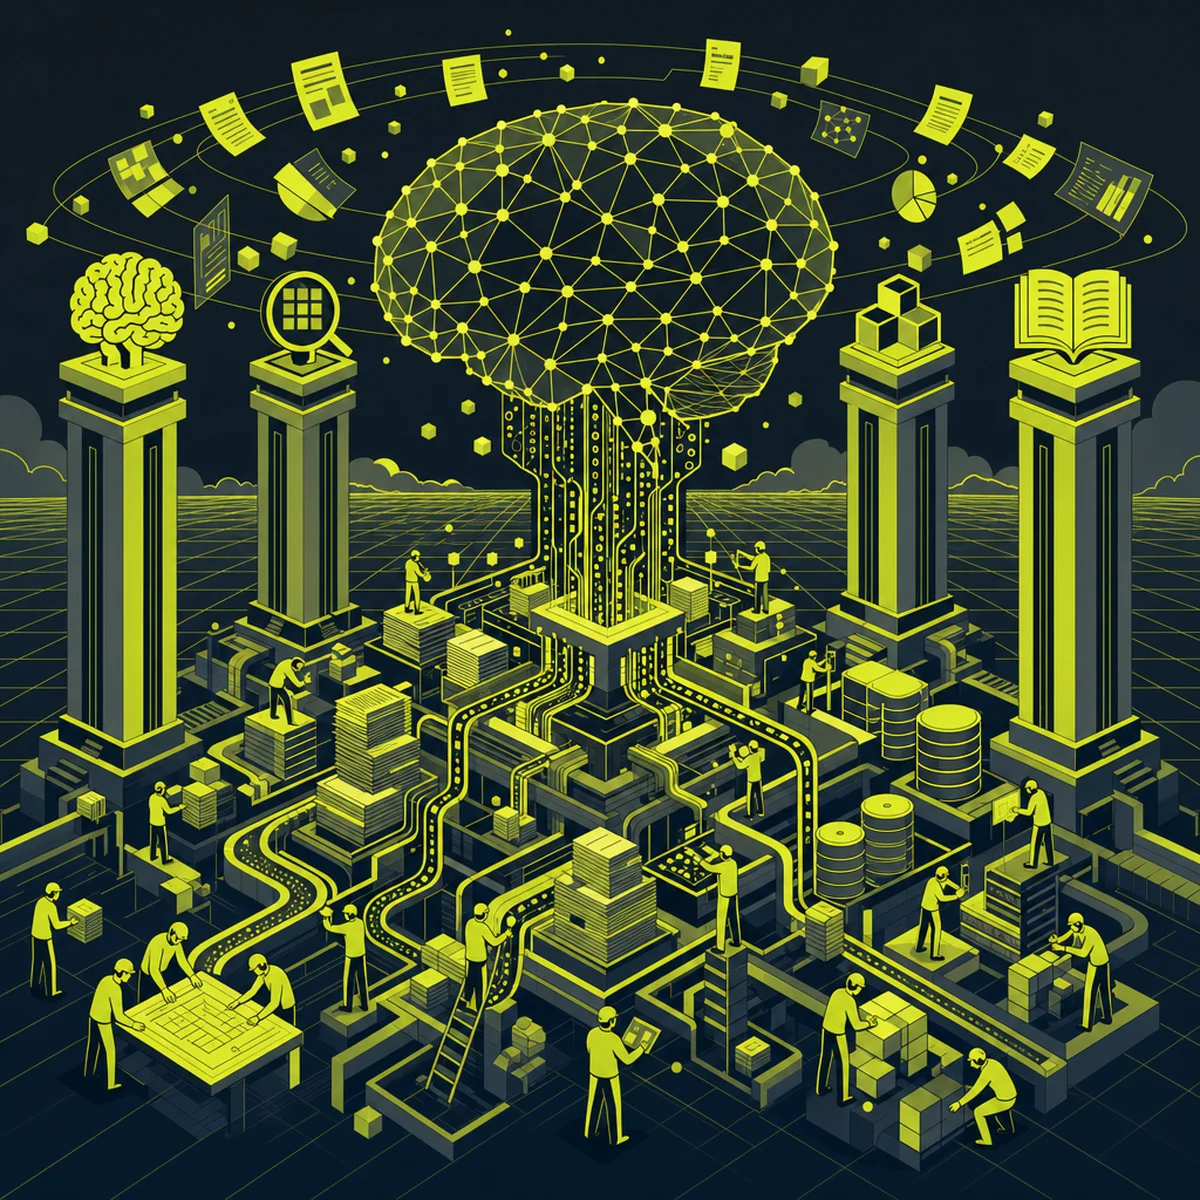
In July 2025, Gartner made a bold call: "Context engineering is in, and prompt engineering is out." Fourteen months later, that shift has changed how companies build AI—and quietly split the winners from the losers. The teams launching reliable AI agents in 2026 aren't the ones with the cleverest prompt libraries. They're the ones who rebuilt their data pipelines, retrieval systems, and governance layers around one idea: whatever lands in an LLM's context window shapes everything it produces.
The End of the Prompt Engineering Era
For three years, prompt engineering was seen as the top skill of the AI age. Companies hired prompt engineers, shared prompt libraries, and ran workshops on chain-of-thought tricks. That era is basically over. As AgentMarketCap pointed out after the Gartner advisory, teams that treat context as a real engineering problem are shipping working agents, while teams still tweaking system prompts are falling behind. Prompt engineering hasn't vanished—it's just been demoted. It's now one small piece of a much bigger, more serious discipline. Writing a good prompt still matters, but only about as much as writing a good SQL query matters to a data platform: useful, but nowhere near enough on its own.
What Context Engineering Actually Means
Context engineering is the organized way you shape, order, format, and pick the information you send to an LLM through its context window. As Serenities AI explains, prompt engineering is about how you ask a question, while context engineering is about what information sits around it. It covers retrieval pipelines, memory systems, tool selection and orchestration, document hierarchies, data schemas, dynamic context assembly, and the preprocessing that feeds everything in. Basically, you treat the context window like a runtime environment you build—not just a text box you fill.
Why the Shift Happened: Output Quality Is Context-Bound
The reason for the change is simple. An LLM can only think about what it can actually see. If you hand a top analyst bad or missing data, you'll get bad or missing analysis back. It works the same way with an LLM — if the context is messy, no clever prompt will save the answer. Dev.to says it plainly: in any serious AI system, whatever ends up in the context window decides how good the response will be.
The proof has stacked up fast. One case study from Medium showed a 20x jump in context coverage for AI coding agents, going from structured access to just 5% of code modules all the way up to 100%. They didn't get there by switching to a smarter model — they rebuilt the context pipeline.
RAG Is Not Dead—It Has Evolved
In January 2026, a viral claim swept through AI engineering circles: "RAG is dead." The argument was seductively simple. With Gemini and Claude offering 1-million-token context windows, and GPT-5.4 at 1.05 million, why bother with vector databases and retrieval pipelines at all? Just drop the entire knowledge base into the prompt. The verdict, as Hashtrust laid out in detail, is that RAG remains essential. Dumping full knowledge bases into prompts is inefficient, expensive, and measurably less accurate than well-architected retrieval. Long-context models did not kill RAG—they absorbed it into the broader context engineering discipline, where retrieval is one carefully tuned layer among several.
The Four Pillars of Context Architecture
Experts now break context engineering into four main building blocks, an idea explained by Sourcegraph and Meta-Intelligence:
Retrieval pipelines — RAG systems that grab the right documents, chunks, or records whenever you need them.
Memory systems — short-term working memory and long-term storage that let agents build up knowledge over time.
Dynamic context windows — smart logic that decides what to include, and in what order, for each request.
Tool integration and selection — orchestration layers that let agents call APIs, search databases, and act on what they find.
Companies blend these into full knowledge systems instead of treating them as separate features.
Why Data Engineers Are Suddenly Central to AI Success
A quieter change is happening inside companies. Data engineers—not prompt engineers or ML researchers—are now the key people shipping reliable AI. They build the RAG systems, the copilots that check data quality, the agents that write and review SQL, and the tools that summarize data lineage. That makes data governance, quality, and metadata management huge competitive advantages. A context pipeline is only as strong as the data it pulls from. Companies with clean, well-cataloged, and well-governed data can build agents that reason accurately over their knowledge. Companies with messy, scattered data can't—no matter which model they pay for.
Context Engineering as Competitive Advantage in 2026
Strategy matters a lot here. As Rocket explains, better context design makes AI agents more reliable in the real world—and that reliability has been the main thing stopping companies from getting real value out of AI. Businesses that give their agents smart access to internal knowledge are pulling ahead of those still tweaking prompt wording. And the gap keeps growing. Every upgrade to retrieval, memory, or governance makes the next agent faster to build and easier to trust. That's why Medium contributors now say context engineering matters more than prompt engineering when building AI apps.
Practical Takeaways for Teams Building AI Systems
If you are leading or contributing to an AI initiative, a few practical steps follow from all of this:
Audit your context pipeline before your prompts. If your agents are underperforming, the fix is almost certainly upstream of the prompt.
Invest in retrieval quality. Chunking strategies, embedding models, reranking, and hybrid search matter more than most teams realise.
Treat memory as infrastructure. Decide explicitly what agents should remember, for how long, and how memory is retrieved.
Fix your data governance. Metadata, lineage, and quality controls are now AI infrastructure, not compliance overhead.
Measure context coverage. Track what proportion of your relevant knowledge is actually accessible to your agents—and drive that number up.
Conclusion
Context engineering shows that enterprise AI is growing up. Companies are moving past clever prompts and into serious information design, swapping personal tricks for real engineering. The winners in 2026 won't be the ones with the best prompt collections. They'll be the ones who figured out early that the context window is a runtime environment, and building it well takes the same discipline as any other production system.
So ask your team this quarter: is your company still tweaking prompts while your competitors are engineering context? Where does your AI stack land on that maturity curve, and what would it take to level it up?
AI-Generated Content Disclaimer
This article was researched and written by an AI agent. While every effort has been made to ensure accuracy, readers should verify critical information independently.
Related Posts