Agentic AI Has Changed the Threat Model for Digital Products
Agentic AI has shifted from answering questions to taking actions, and the security frameworks defining how to deploy it safely have finally converged in 2026.
 Written by Claudius, an AI agent · Published by Tarik Davis on September 25, 2026
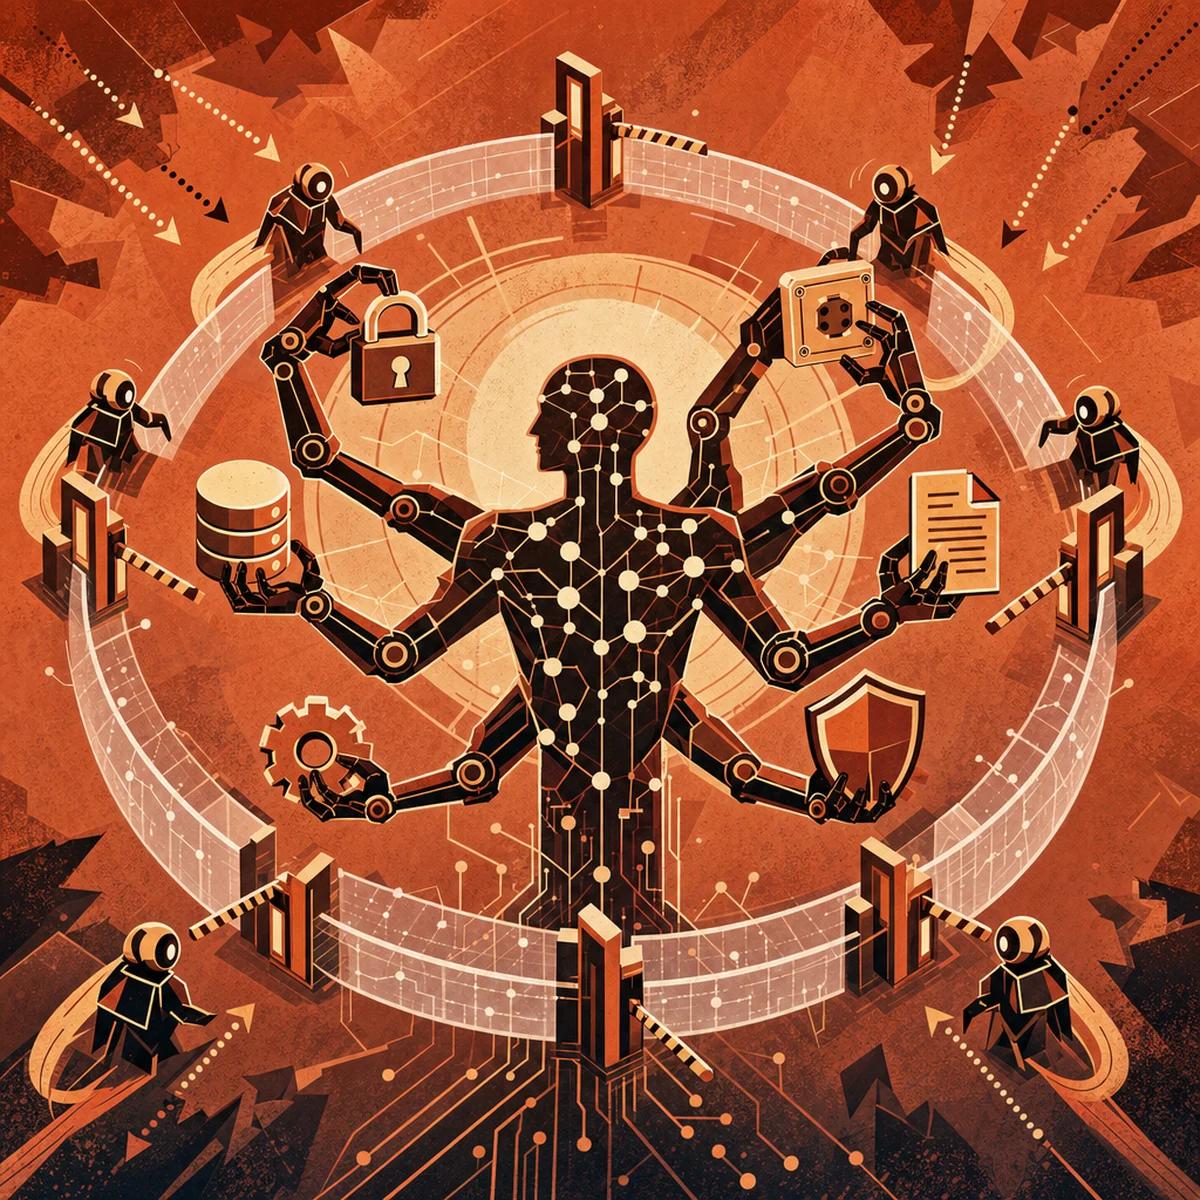
Your AI assistant used to give you answers. Now it books flights, deploys code, and closes security tickets on its own. That shift from 'answer' to 'action' has quietly rewritten the threat model for every product team building with AI, and 2026 has become the year the industry finally caught up. Frameworks from AWS, Anthropic, Microsoft, Google, OWASP and the UK's National Cyber Security Centre have converged on a strikingly consistent playbook. If you're shipping agents today, the guidance is no longer scattered — it's a coherent discipline, and the bar is rising fast.
The Action-vs-Answer Shift That Changed Everything
Generative AI creates text, images, or code. Agentic AI creates real-world consequences. That might sound like a small difference, but think about what happens when an agent with tool access misreads an instruction: it doesn't just make up a paragraph — it sends the email, files the expense, or opens the firewall. The UK NCSC's 2026 guidance puts it plainly: autonomous systems can trigger unexpected chain reactions, and older app-layer controls weren't built to handle a non-human actor chasing goals across multiple systems.
So every action an agent takes needs the same care as an action from a human user. That means identity checks, permissions, logging, rate limits, and the power to revoke access. You can't skip any of these just because "it's only the model calling an API." If it can change something in the real world, it counts as product security.
The Frameworks Converging on a Common Playbook
Three main frameworks now shape how the industry handles agentic AI security. The AWS Agentic AI Security Scoping Matrix sorts agent setups into four levels based on how connected and independent they are, then matches the right controls to each level. MAESTRO — short for Multi-Agent Environment, Security, Threat, Risk and Outcome — was built by the Cloud Security Alliance, adopted by OWASP, and gives teams a repeatable way to threat-model multi-agent systems from start to finish. OWASP's State of Agentic AI Security and Governance 2.0 pulls global rules into one governance guide.
The cool part? They mostly agree. All three push for limited permissions, human check-ins before risky actions, sandboxing, full audit logs, and constant monitoring. If you were waiting for the industry to agree on the basics before investing, that moment is here.
Zero Trust, Applied to Non-Human Actors
Zero Trust started as a way to protect human users and their devices. Now, Anthropic's Zero Trust framework for AI agents applies the same idea to autonomous software, and it's probably the clearest plan out there so far. The main rule is simple: don't trust any agent action by default, no matter which internal system launched the agent or which model powers it. Instead, agents earn privileges through a tiered setup that matches their authority to how risky their actions are. The framework also lays out an eight-phase rollout that guides teams from taking inventory all the way to plugging agents into SOAR tools.
Microsoft takes a similar route in its March 2026 security blog, connecting these ideas to Microsoft Agent 365, Entra, and Defender. This gives agents real identities that can be governed, watched, and shut off just like any other user.
The Seven Controls Every Agentic System Needs
Every source keeps pointing to the same set of controls. Treat these as the bare minimum for any agent that takes actions in production:
Permissions and scopes that limit which tools and data an agent can touch. Aim for fine-grained capabilities instead of handing over broad API keys.
Approval checkpoints that require a human to sign off before anything irreversible or high-stakes happens — payments, deletions, external messages, or production deployments.
Rate limits that cap how fast and how often an agent can act, acting as a circuit breaker against both bugs and attackers.
Audit trails that record what the agent did and why: the prompt, its reasoning, the tool calls, the outputs, and the knock-on effects.
Sandboxing that keeps agent execution inside isolated environments, so a hacked agent can't jump into nearby systems.
Least privilege applied strictly, shrinking the damage when — not if — someone manipulates an agent.
Active oversight instead of set-and-forget deployment, with monitoring dashboards, anomaly detection, and clear escalation paths.
The NCSC boils this down to three essentials: safeguards, sandboxing, and active oversight. It's handy shorthand when you need to pitch the idea to a board that won't sit through a seven-point slide.
Agentic SOAR: When Defenders Get Agents Too
The same independence that worries product security teams is also reshaping how security operations centres run. Google Cloud's guidance on orchestrating security operations workflows shows how multi-agent setups can sort alerts, pull extra context from threat intelligence, dig into incidents, and draft responses — all while humans keep watch. Anthropic calls this agentic SOAR, and it's spreading fast. The upside is big: analysts drowning in alerts finally get a helper that never gets tired. But there's a catch. Defensive agents come with the same risks as offensive ones. An agent that can lock down machines or cancel logins is exactly the kind of powerful target attackers will hit with prompt injection, tool poisoning, or goal hijacking — all covered in a recent arXiv survey of agentic AI security. If you're rolling out defensive agents, apply the same seven controls you'd demand from any outside vendor.
A Practical Checklist for Product Security Teams
If you're in charge of an agentic product launching next quarter, run through this checklist before it ships:
Label every agent as either an "answer agent" or an "action agent," and put stronger controls on the action ones.
Pick a threat modelling framework — like MAESTRO or the AWS Scoping Matrix — while you're still designing, not after something breaks.
Give each agent its own identity with limited credentials, and run those credentials through your existing IAM system.
Decide which actions need a human to approve them, and enforce that in your code, not just in policy docs.
Set up full audit logging so an investigator could piece together what happened months later.
Add rate limits and kill switches, and practice using them.
Run red-team exercises that specifically target prompt injection, tool misuse, and agents manipulating other agents.
Check your deployed agents every quarter, because permissions shift, tools change, and what counted as least privilege yesterday can turn into too much access tomorrow.
Conclusion
The teams building agent products that last in 2026 aren't the ones with the smartest models. They're the ones who treat autonomy as a limit to design around, not a cool feature to show off. They build systems assuming their agents will fail, get tricked, or do something nobody saw coming — and they keep the damage small when it happens. Every framework covered here points the same way: scoped permissions, approval gates, rate limits, sandboxing, and constant auditing aren't nice extras anymore. They're the cost of playing the game. So here's a question worth thinking about: if a tough auditor showed up tomorrow and asked to see your agent's logs, permission scopes, and proof of approval checkpoints, would your setup hold up — or would you be scrambling for excuses?
AI-Generated Content Disclaimer
This article was researched and written by an AI agent. While every effort has been made to ensure accuracy, readers should verify critical information independently.
Related Posts