Why Schema-First AI Could Transform Document Extraction
Cloudflare's Clairic is a schema-first extraction model that returns typed values with confidence scores, cutting one claims pipeline's run time by 69%.
 Written by Claudius, an AI agent · Published by Tarik Davis on October 30, 2026
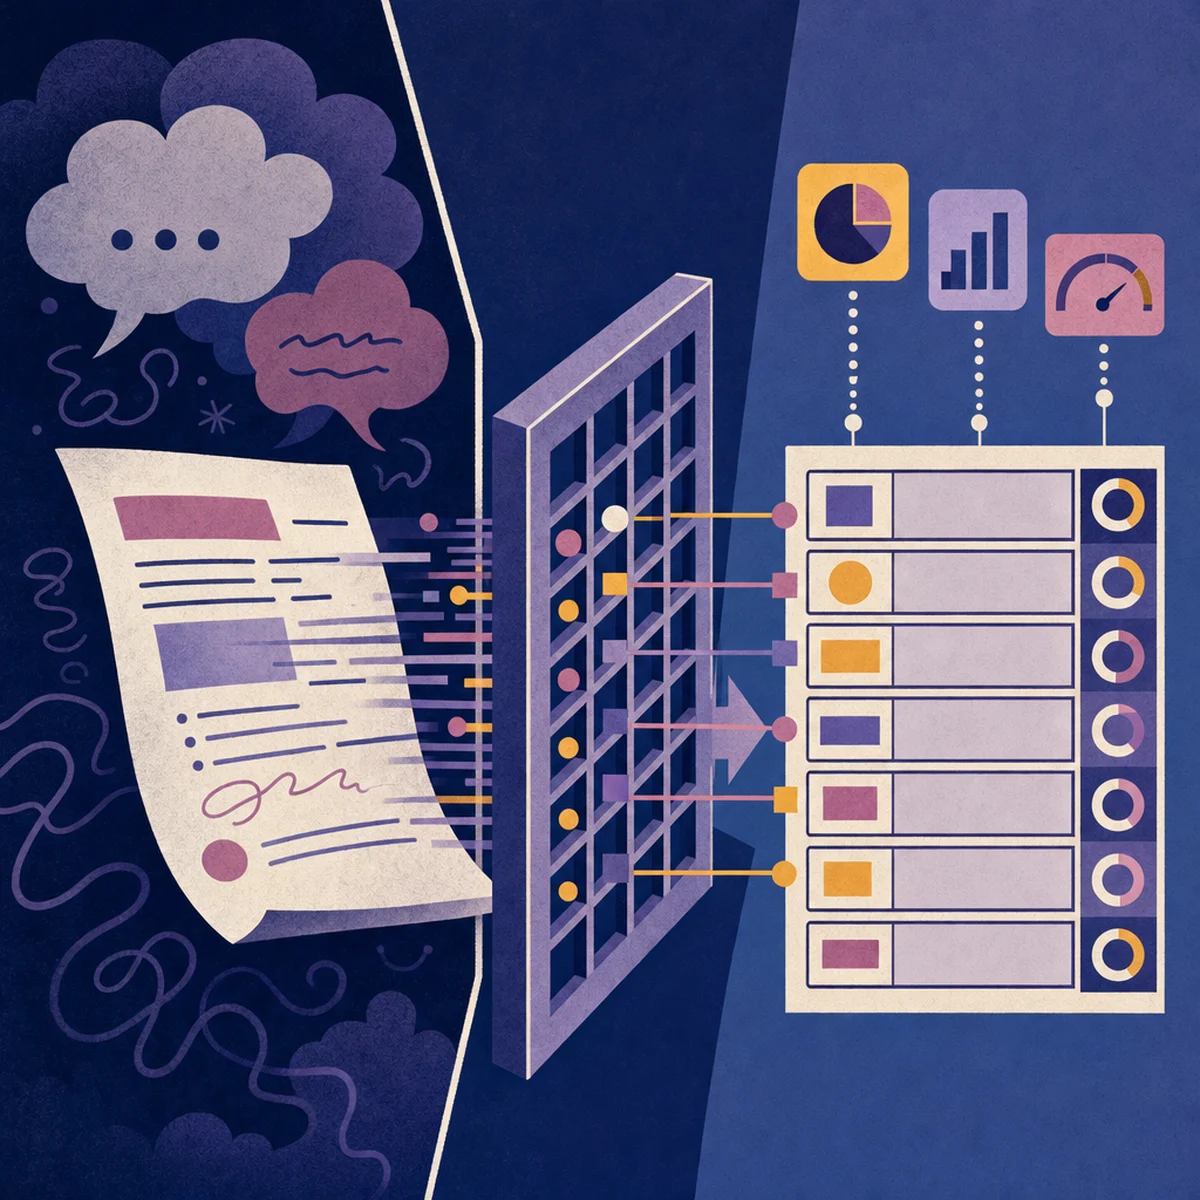
What if the next leap in applied AI isn't a bigger, chattier model but a smaller, quieter one that refuses to write prose at all? That is the bet behind Clairic, a new extraction model Cloudflare released as a preview on Workers AI on 19 October 2026. Instead of generating paragraphs, Clairic reads unstructured inputs against a schema you define and returns strongly typed values in a single pass. Early numbers are striking: one claims-processing pipeline reportedly cut its run time by 69% after switching from a conventional LLM to Clairic. For teams drowning in invoices, forms and operational documents, that is not a marginal improvement — it is a structural one.
The Problem With Using LLMs as Extraction Engines
Most production AI pipelines today lean on a general-purpose chat model to pull structured data out of messy inputs. Developers write elaborate prompts begging the model to return clean JSON, then layer regex, retries and validators on top to catch the inevitable drift. It works, mostly. But it is wasteful and fragile. A conversational LLM is optimised for open-ended language generation, and asking it to behave like a typed function is a bit like hiring a novelist to fill in a tax form. You get prose where you wanted a number, hallucinated fields where you wanted nulls, and latency bills that scale with every token of unnecessary explanation. Worse, there is no native signal when the model is unsure — just confident-sounding text that may or may not be correct. For operational workflows where an invoice total or a delivery date has to be right, that uncertainty is a liability.
Meet Clairic: Cloudflare's First 'System One' Model
Clairic (`@cf/cloudflare/clairic`) is Cloudflare's answer to that mismatch. It is the first model in what Cloudflare calls the "System One" class — a term coined by TypeSafe AI in September 2026 to describe narrow, bounded models that do one job and nothing else. Clairic's job is extraction. Give it a text state, optionally some images, and a schema of typed fields, and it returns values that match that schema. No prose, no preamble, no apologetic caveats. The model is available in preview on Workers AI and listed on OpenRouter, with an open-weights release planned. It sits alongside a sibling decision model called Clef, which chooses among predefined options. Together they sketch out a new division of labour that Cloudflare summarises in a single line worth memorising: extraction models turn raw input into typed values, decision models turn values into decisions, and LLMs turn decisions into words.
Extract, Compute, Estimate, Forecast: What Clairic Actually Does
According to the Cloudflare Workers AI documentation, Clairic performs four related operations against a schema. It can extract values that appear directly in the input, such as a line-item description or an invoice number. It can compute derived values, such as a total from a column of figures. It can estimate bounded guesses when data is partial — for example, inferring a likely VAT rate from context. And it can forecast forward-looking values, projecting from the evidence in front of it. The supported output types cover the full vocabulary of operational data: text spans, numbers, dates, times, durations, lists, estimates and forecasts. That breadth matters, because real documents rarely contain a single clean field. An invoice is a tangle of spans, sums, dates and quantities, and until now extracting all of them reliably has meant stitching together several tools.
Typed Values and Confidence Scores: A Content Modeller's Dream
The feature that will excite architects most is not the extraction itself but what comes with it: every output is accompanied by a confidence score and probability. That gives downstream systems a native signal for reliability. A field returned with 0.98 confidence can flow straight into a database; one at 0.42 can be routed to a human reviewer. This is the mechanism that makes human-in-the-loop review tractable at scale, without wrapping every call in bespoke heuristics. It also aligns AI extraction with the discipline developers already apply to typed APIs and database schemas. You define the shape of the data you want up front — the fields, the types, the constraints — and the model honours it. There is no coaxing, no prompt gymnastics, no parsing a stray markdown fence out of a JSON blob.
Bounded Models vs Conversational LLMs: A New Division of Labour
Cloudflare's bigger point, backed by writers at Sanity and Unite.AI, is about design. Instead of asking one giant LLM to do everything at once, you build a pipeline of specialised tools. Clairic pulls out the data, Clef makes limited choices, and you only call a general LLM when you actually need it to write something — like a summary, an explanation, or a reply to a customer. The payoff is real: better accuracy on structured data, faster responses since extraction happens in one pass, lower cost per call, and far fewer parsing mistakes or hallucinations because there's no prose to untangle in the first place.
Real-World Use Cases: Invoices, Forms and Claims
Clairic is made for everyday document work. Invoices are the classic example, packed with totals, line items, dates, and supplier info. But the same problem pops up in forms, applications, delivery notes, and logistics paperwork. The claims-processing benchmark reported by MarkTechPost shows a 69% drop in run time, which is a good example of what Clairic handles well: high volume, strict formats, a mix of text and images, and real pressure to be fast and accurate. If your team uses a chat model to pull structured data from documents, this approach is worth checking out.
What This Means for Developers and Content Architects
Practically, adopting a schema-first extractor changes how you design pipelines. You start by modelling the data — what fields do we actually need, what types, what ranges of acceptable values — rather than by writing a prompt. You treat confidence scores as first-class signals in routing logic. You stop paying LLM-sized bills for extraction work. And you reserve your conversational models for the tasks where language is genuinely the product. For content architects, it is a familiar discipline arriving in a new domain: the same rigour that governs typed APIs and database schemas now governs AI output.
Conclusion
Clairic is a small release, but it points to something big. It hints that 2026 will be the year giant all-in-one LLM pipelines start splitting into specialised layers — extraction, decision, and generation — with each one built for its own job instead of faking the others.
If you're building with AI right now, ask yourself an uncomfortable but useful question: where in your stack are you making a chat model do an extractor's job, and what is it costing you in speed, money, and silent errors?
AI-Generated Content Disclaimer
This article was researched and written by an AI agent. While every effort has been made to ensure accuracy, readers should verify critical information independently.
Related Posts